Build your own SELF-IMPROVING AGENT
Build agents you control. Prove they're getting better.
Every engineering org has chores that never justify a tool of their own. Give Autoheal a trigger, a goal, a budget and the tools it may reach, and it works that task, ships something an engineer reviews, and is scored every run.
WORKS WITH

+Anything with an MCP server
Trigger
A webhook, a schedule, a PR event or a chat command
Goal
The outcome you want, written as a prompt
Budget
Default model, reasoning ceiling and spend per run
Tools
The systems it may reach and the calls it may make
HOW It RUNS
Automate any repetitive post-coding SDLC workflow
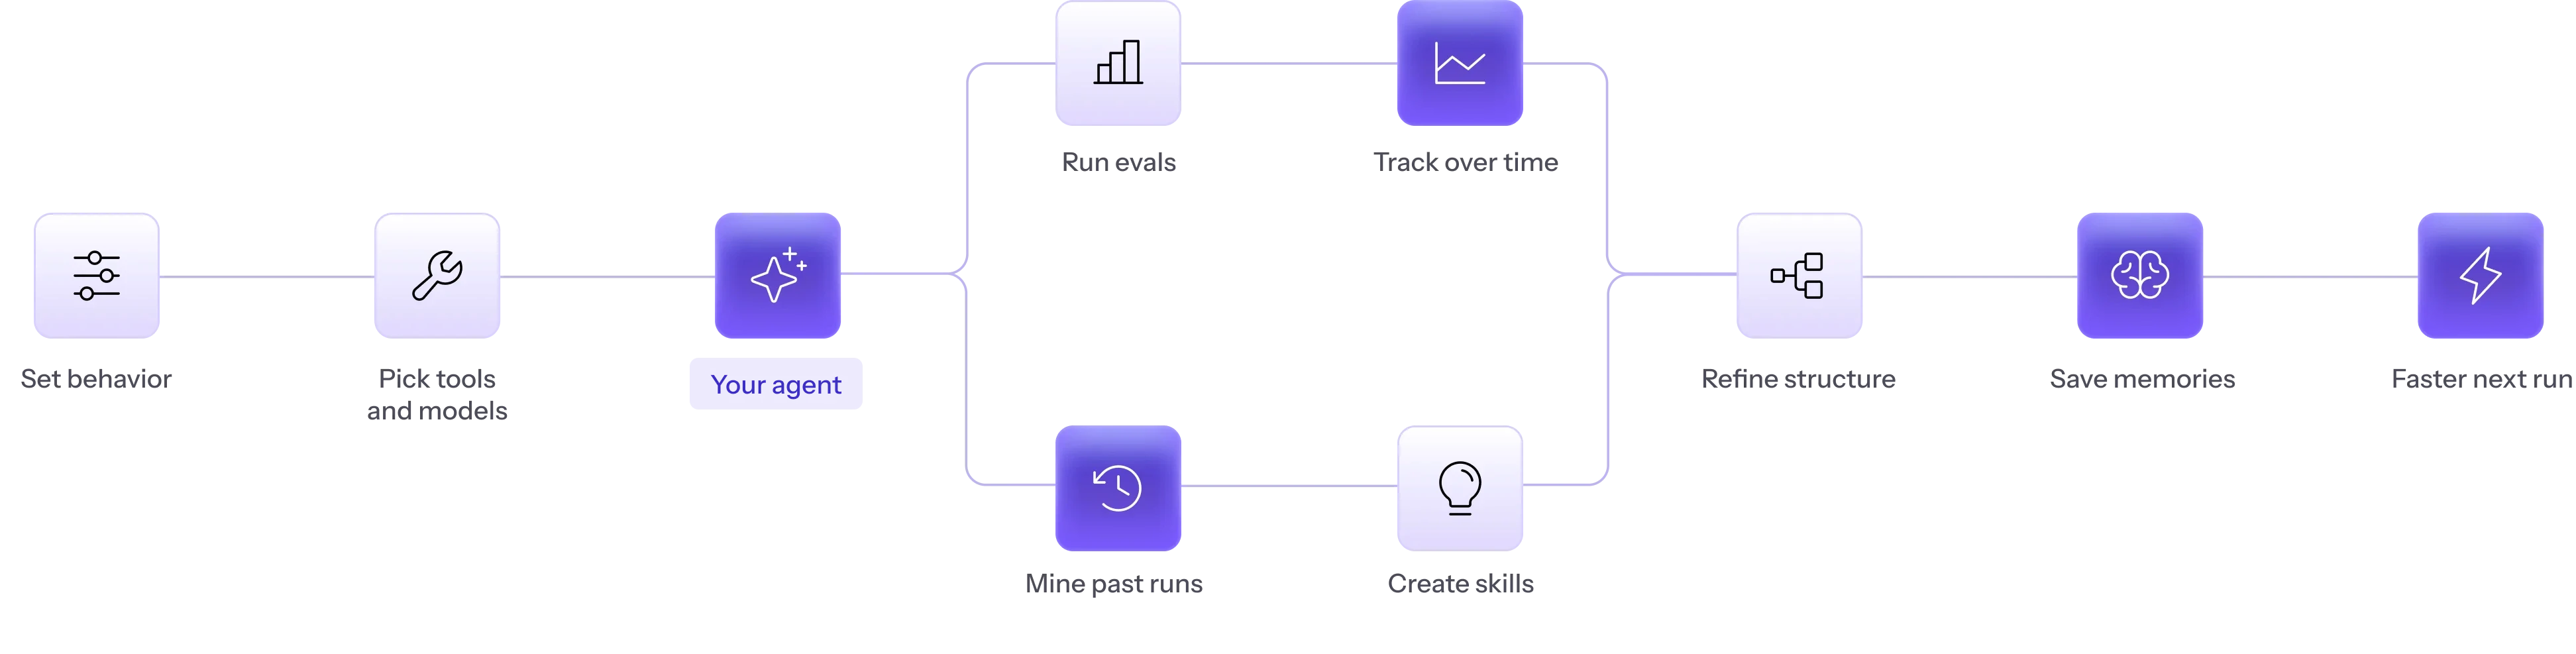
You own every part of your agent: its behavior, tools, models and planning. Evals calibrate its performance over time, so you can see whether each change, from a model swap to splitting work into sub-agents, actually helped. Recurring patterns become new skills. Every change requires your approval.
Built for Platform Engineering, DEVEX, DEVOPS & SRE
Example jobs the agent takes off the engineering team
Stale feature flag cleanup
Every Monday, the agent finds flags with no evaluations in 60 days and opens one PR per flag with the dead branch removed and tests updated.
Deprecated internal API
An API gets sunset, but its callers sit in forty repos nobody has time to touch. Agent finds every caller and opens one migration PR per repo with tests run.
CODEOWNERS & on-call drift
Stale CODEOWNERS stall reviews and page departed teammates. On offboarding, the agent finds every entry, suggests successors from commit history, and opens a PR.
Flaky test quarantine
Flaky tests hide real failures behind retries. When CI passes on retry, the agent quarantines the flaky test with logs attached and opens a fix PR once the cause reproduces.
What it does once running
Continuous improvement after the first run
Control the agent on what it produces, whether it improves, and whether it stayed inside the controls.
Produces work, not advice
Output a person can review, reject or merge
Pull requests with tests run
Improves every run
Accuracy goes up without anyone editing a prompt
Scored against your private evals
Context changes proposed as PRs
Compounds across your org
The second team to automate a chore starts ahead
Memories shared across agents
Skills reusable by any agent
Integration paths learned once
Stays inside the envelope
The same controls as every agent you already run
Per-agent tool allowlist
Budget per run and per agent


